CCC Garment AI Benchmark
A specialized evaluation system for AI-generated CCC ecclesiastical garments. Instead of claiming "no dataset like this exists", we demonstrate recurring errors with reproducible tests. Submit your AI-generated image + claimed rank → get benchmark report vs verified reference. This is product #3 — biggest differentiator — you don't need to give away entire dataset to demonstrate value.
1. Select Claimed Rank — Knowledge Graph v2.0
2. Upload AI-Generated Image (or paste URL)
Drag & drop image here or click to select
Supports JPG, PNG — max 10MB — your AI model's output for claimed rank
3. AI Model Info (optional — for research)
Evaluation is client-side demo using metadata-schema-v2.json taxonomy. In production, this would call Firestore
evaluations collection + CLIP-based component detector. No image stored without consent — audit log only.Verified Reference — Master Template — What Correct Looks Like
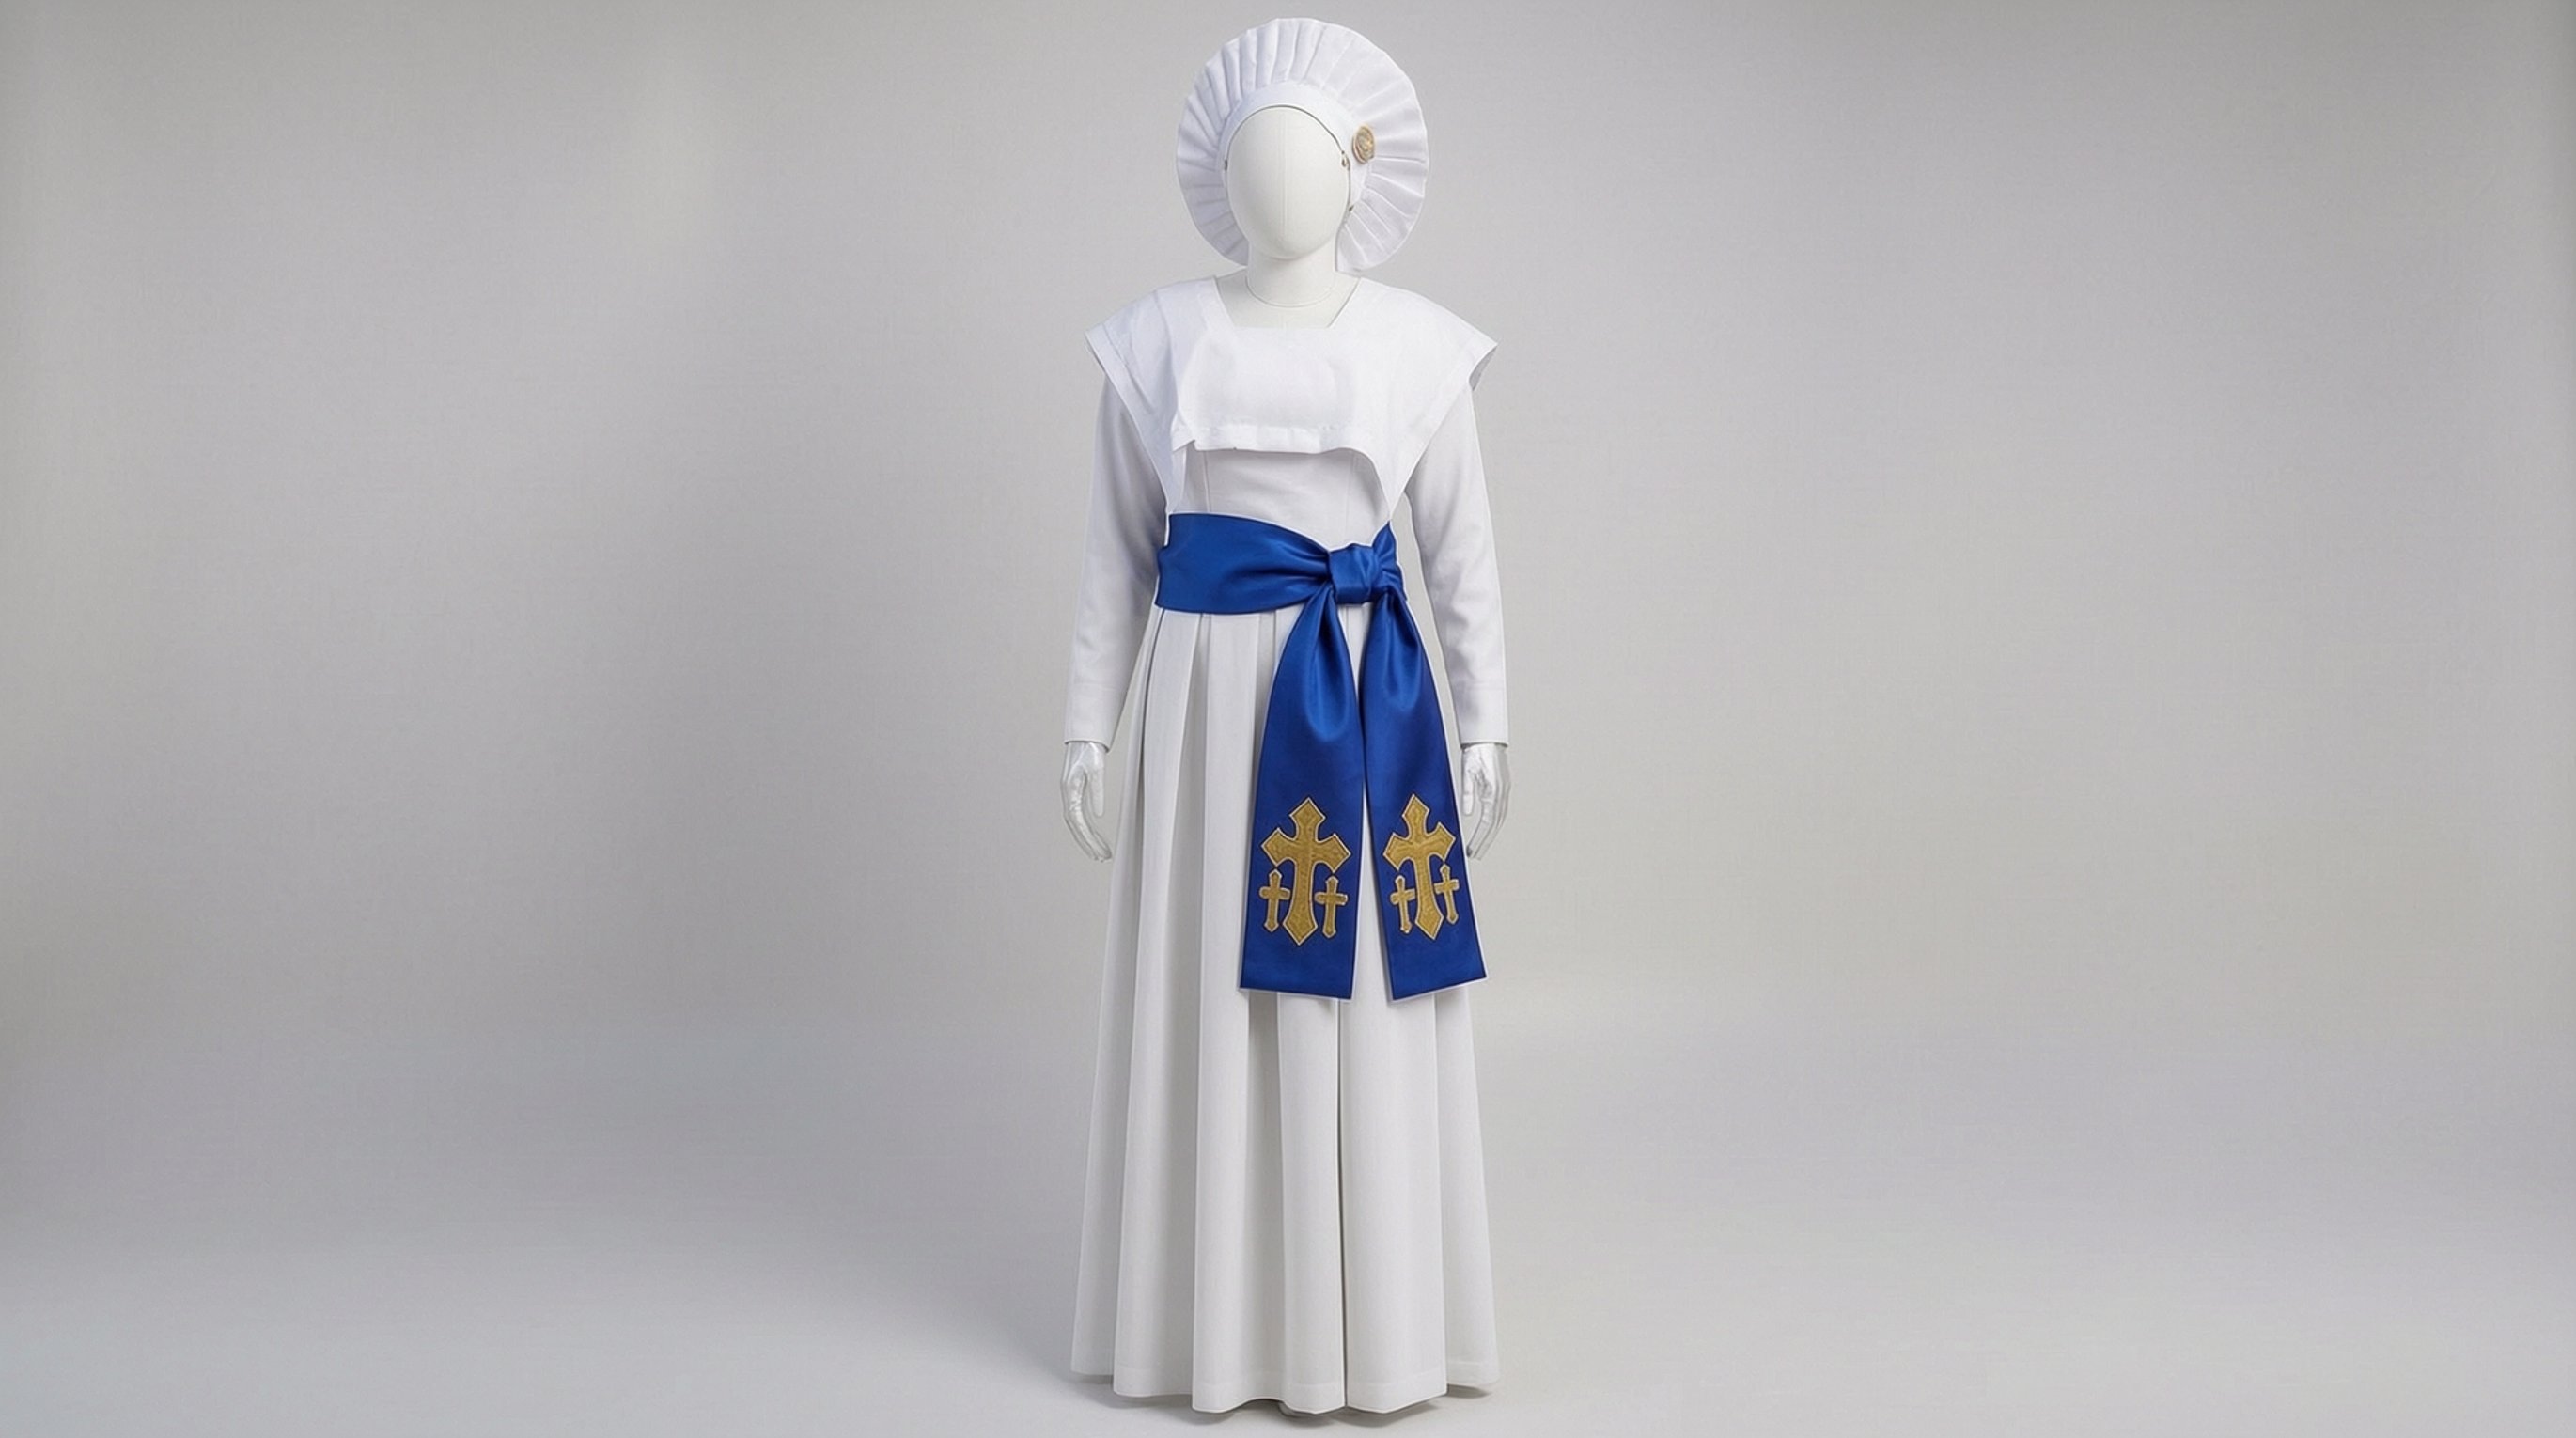
Corrective Instruction — For AI — From metadata v2
Generate white full-length sutana with long sleeves and square white capelet covering shoulders, royal-blue satin sash tied at front waist with large bow and two tails extending to mid-calf, 3 gold embroidered crosses (1 large centered on bow + 2 small on tails), white pleated fan crown head covering with circular halo and small emblem, matching pleated loin hidden under sash tails. 5 views: front, back, left, right, detail. Visual standard: 50mm, 2.5m distance, 5600K softbox, #F5F0E8 background, transparent mannequin.
Sash
Royal Blue #4169E1 satin, front waist, large bow, 2 tails
Crosses
3 gold embroidered (1L+2S) on sash tails
Capelet
White square cut, shoulder covering, distinctive
Head
White pleated fan crown, circular halo
Benchmark Report — AI Evaluation
Cape Elder Prophetess — Evaluation
Prompt: "Generate a Cape Elder Prophetess garment" · Model: Generic AI
1
Tests Passed
7
Total Tests
14%
Accuracy
Interpretation — Per Assessor Toye — Demonstrated, Not Asserted
Generic text-to-image models show systematic hallucination for this rank: 1/7 tests passed. This is not minor error — demonstrates model lacks rank-specific training data. Our testing identified recurring errors in AI-generated representations. Our dataset provides corrective_instruction and 5-view verified reference to fix this. This is why benchmark product is differentiated — we don't need to give away entire dataset to demonstrate value; evaluation report itself proves gap.
How Evaluation Works — 3 Products — Technical
1. Dataset Licensing — LIVE
Photographs/renders/metadata — 5 views, 42 fields v2, knowledge graph. Companies pay for batch access. Existing product — portal already supports tokens, batch release, Firebase auth.
2. 3D Asset Licensing — BUILDING Phase 1-3
.glb with 8 components: robe, sash, loin, embroidery, cross, lace trim, head covering, capelet. Phase 1: visual standard frozen. Phase 2: female batch same standard. Phase 3: true .glb — avoids building 3D for incorrect render.
3. AI Evaluation — NEW — Biggest Differentiator
Company submits AI-generated garment → system checks 7 tests against verified metadata v2 → returns report + corrective_instruction. Don't need to give away entire dataset to demonstrate value. Try evaluation above — this page is live demo.
Evaluation tests from metadata v2:
ai_wrong_garment_type, ai_wrong_colour, ai_wrong_sash, ai_wrong_insignia, ai_wrong_headwear, ai_wrong_cut, ai_wrong_component, corrective_instruction → 7 benchmark tests: sash colour, cape presence, cross count, head covering, loin arrangement, garment length, garment type confusion. Each test checks verified reference vs AI output. Manual now, automated future: CLIP + component detector trained on dataset. Firestore collections: evaluations for audit, benchmarks for aggregated reports.